The best Playwright alternative

Playwright turns browser behavior into code you maintain. ego(lite) turns the browser into a workspace your coding agent can use. ego(lite) completed 93.5% of tasks perfectly in our published benchmark of 31 live-site browser automation jobs, the highest perfect-completion rate measured.

ego(lite) vs Playwright

Feature comparison between ego(lite) and Playwright.
Featureego(lite)Playwright
How work gets doneDescribe the task; your agent drives the browserWrite and maintain TS/Python/Java/.NET scripts
Handles page changesAgent re-reads the Snapshot and adaptsLocators break; you update the code
Logged-in sites (SSO, 2FA)Inherits your real Chrome profile and sessionsBlank contexts; script logins, manage storageState
SetupInstall the app, run /ego-browser in your agentNode/Python project, install browsers, config file
Works with AI agentsBuilt for them: Claude Code, Codex, Cursor via ego-browserVia codegen, playwright-cli, or the separate Playwright MCP server
Browser automation on live sites (31 tasks, same model)93.5% perfect, $1.75 per completed task, 6m 38s average71% perfect, $4.82 per completed task, 10m 48s average (via playwright-cli)
Parallel tasksSpaces isolate tasks inside one visible browserWorkers and contexts, typically headless
Daily-use browserYes, you browse in your Space while agents work in theirsNo, an automation library, not a browser you live in
CI test suitesNot a test runner; agents handle browser work directlyYes, the strongest test runner and CI story around
Reusable skills (coming soon)Distills successful runs into reusable skills for repeat tasks (limited beta)No built-in equivalent
PriceFree, no subscriptionFree, open source

Last updated Aug 30, 2026

Trusted by developers from

  • Vercel
  • OpenAI
  • Anthropic
  • SpaceX
  • Google
  • Microsoft
  • DJI
  • DeepSeek
  • Kimi
  • TikTok
  • MiniMax
  • SAP
  • ZARA
  • eBay
  • Cisco
  • Trip.com
  • LINE
  • NHN
  • Hyundai Motor

Browser automation benchmark: ego(lite) vs Playwright

This benchmark measures agent browsing on live websites rather than a scripted test suite: 31 multi-step jobs, many behind login walls, run end to end by ego(lite) and agent-driven Playwright.

agent: pi · model: ChatGPT 5.6 Sol · thinking: max · 31 tasks

  1. ego(lite)93.5%
  2. playwright-cli71.0%

Task completion rate

Every tool got the same 31 tasks: multi-step jobs on live websites, many behind login walls. A task counts only when every requirement is met. No partial credit. Tasks no pre-written script survives: estimate a mortgage on Redfin behind a login, chase two tickets through a live on-sale, rank the best-reviewed Action RPGs across PS5 and PC.

agent: pi · model: ChatGPT 5.6 Sol · thinking: max · 31 tasks

  1. ego(lite)
    93.5%
  2. playwright-cli
    71.0%

Cost per completed task

Failed runs still bill you. This divides total model spend by tasks actually completed, so it prices what a result really costs. Lower is better.

agent: pi · model: ChatGPT 5.6 Sol · thinking: max · 31 tasks

  1. ego(lite)
    $1.75
  2. playwright-cli
    $4.82

Efficiency score

Rubric points earned per thousand model turns: how much finished work each model call buys. Higher is better.

agent: pi · model: ChatGPT 5.6 Sol · thinking: max · 31 tasks

  1. ego(lite)
    6.16
  2. playwright-cli
    4.15

Average task time

Average wall-clock time per task across all 31. ego(lite) finished tasks 63% faster than playwright-cli.

agent: pi · model: ChatGPT 5.6 Sol · thinking: max · 31 tasks

  1. ego(lite)
    6m 38s
  2. playwright-cli
    10m 48s

Real-World Bench is an open-source benchmark: 31 complex real-world browser automation tasks on live websites, every tool driven by the same pi agent with the same model (gpt-5.6-sol, thinking effort max) and graded by the same judge against per-task rubrics. Every score covers all 31 tasks, with no per-task cherry-picking. The bench drives Playwright through playwright-cli, the companion CLI the Playwright team ships for coding agents, which is the strongest agent-facing way to run Playwright today.

Why ego(lite) is better than Playwright

The difference is where the workflow lives. Playwright asks you to author and evolve the automation; ego(lite) lets your agent work from the outcome you want, across search, research, data extraction, forms, testing, and everyday web tasks. It can use your authorized browser state and its own Space, so the work stays visible without taking over your tabs.

93.5% of tasks done perfectly. No other tool tops 78%

A Playwright script survives about as long as the page it was recorded against. Codegen locators capture one DOM snapshot, and a redesign a few months later leaves you patching selectors instead of shipping. Even driven by an agent through Microsoft's own playwright-cli, 29% of those 31 live-site tasks ended short of a perfect score.In ego(lite), your agent reads the page as a compressed Snapshot with stable @N refs and writes the JavaScript itself, so it adapts when the page changes instead of breaking: 93.5% of the same 31 tasks ended perfect, 63% faster than agent-driven Playwright on average task time.

Time to finish a task, shorter is better

  1. ego(lite)
    398 s
  2. playwright-cli
    648 s

Data source - Task: finish an average live-site job

Parallel multitasking, execute faster

Playwright's parallel test runs are headless by default. Headed mode scatters a separate OS window per worker with no way to pause one and take over, so most teams leave it headless and review a trace file afterward.In ego(lite) there's no cap on how many Spaces you open: each runs its own task at once, on its own imported Chrome profile, and none of them ever steals the tab you're using. Watch or take over any Space anytime, live.

No more back and forth Cost fewer tokens

Drive Playwright from an agent through Microsoft's own playwright-cli, and you're still issuing one command per action: snapshot, click a ref, snapshot again, read the result, decide the next command.In ego(lite), the agent batches several actions into one JavaScript call per turn and reads the page as a compressed Snapshot instead of a full accessibility dump. Stacked together, that brings the whole task down to far fewer tokens overall.

Claude Code · ego(lite)
>/ego-browser Add the first product to the cart, then check checkout loads
●Bash(
ego-browser nodejs <<'EOF' await openOrReuseTab('localhost:3000') await click('.product-card') await click('.add-to-cart') await click('a[href="/checkout"]') cliLog('checkout loaded') EOF
)
⎿Output:
[t=4480ms] checkout loaded
Done. Both steps work.
─── 1 tool call · ↑ 1.1k tokens ───
Claude Code · playwright-cli
>Add the first product to the cart, then check checkout loads
$playwright-cli open localhost:3000
⎿stdout
Opened http://localhost:3000
↑ 1.6k tokens sent so far
Storefront loaded. Snapshotting to find the first product.
$playwright-cli snapshot
⎿Snapshot
… +224 lines (ctrl+o to expand)
↑ 3.1k tokens sent so far
First product card is e12. Clicking it.
$playwright-cli click e12
⎿stdout
Clicked e12
↑ 4.9k tokens sent so far
Product page is up, refs are stale. Snapshotting again.
$playwright-cli snapshot
⎿Snapshot
… +205 lines (ctrl+o to expand)
↑ 6.8k tokens sent so far
Add to cart button is e8.
$playwright-cli click e8
⎿stdout
Clicked e8
↑ 9.2k tokens sent so far
Added. Heading to checkout.
$playwright-cli click e21
⎿stdout
Clicked e21
↑ 11.2k tokens sent so far
Confirming the checkout page actually rendered.
$playwright-cli snapshot
⎿Snapshot
… +229 lines (ctrl+o to expand)
↑ 13.6k tokens sent so far
─── 7 tool calls · ↑ 13.6k tokens ───

The same task, the same model. Left: one batched JavaScript call in ego(lite), 1.1k tokens total. Right: Playwright driven through playwright-cli, 7 round trips, tokens climb to 13.6k.

Same Chrome, agent-native

A fresh Playwright context starts blank, so real auth means scripting the login, saving storageState, and hoping the tokens outlive your test run. When a provider rotates refresh tokens, the way Auth0 does under MFA, the saved state breaks anyway.ego(lite) imports your entire Chrome profile in one click: cookies, sessions, and extensions all come with it, so the agent starts already signed in everywhere you are.

Make it a seamless transition

You don't port Playwright tests to ego(lite). Keep them. What moves over is browser work you want an agent to handle directly: search, research, extraction, forms, testing, and logged-in workflows outside your CI suite.

1

Download ego(lite)

Download ego(lite) and import your Chrome profile in one click. The logins your test contexts never had come along too.

2

Run your first task with /ego-browser

Run /ego-browser in Claude Code, Codex, or Cursor. No project scaffold, no playwright.config.

Paste into your agent

/ego-browser Open ego.app and list every link in the nav bar

3

Watch it work

Hand the agent a task you'd normally write a script for, like pulling numbers from a logged-in dashboard or walking a checkout flow, described in a sentence.

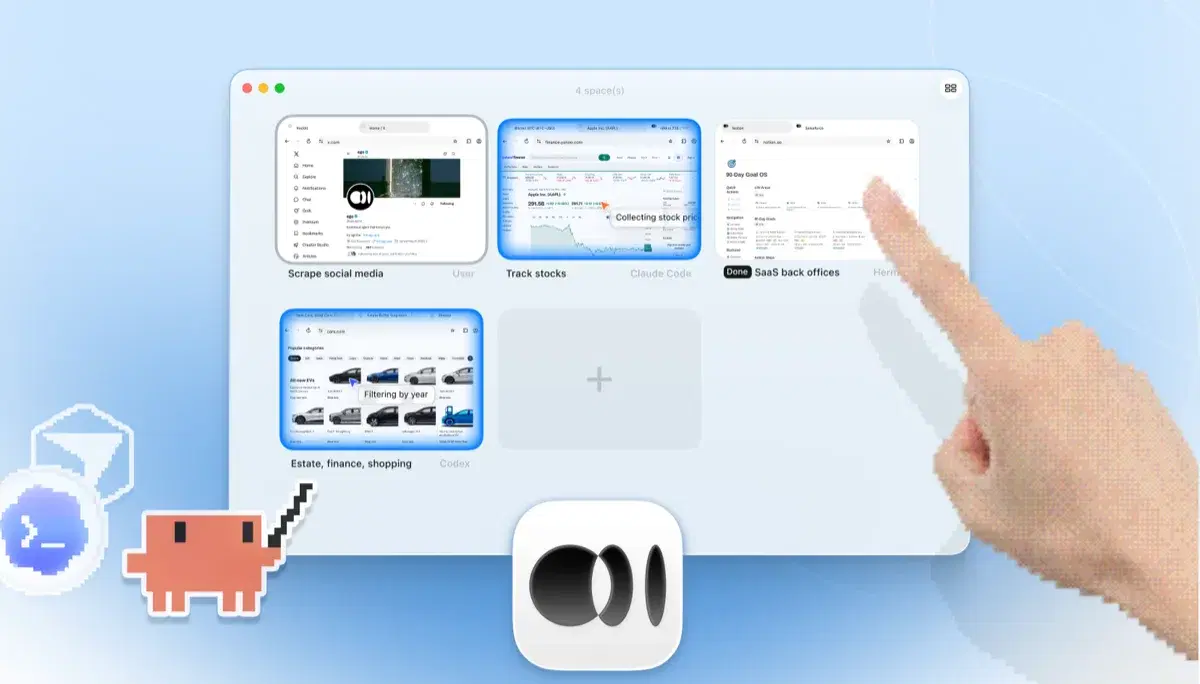
ego(lite) Spaces overview with four browser tasks running side by side: Claude Code tracking Apple stock on Yahoo Finance, Codex filtering cars by year on cars.com, Hermes finishing a SaaS back-office task, a user scraping X, and a hand tapping + to open another Space

Keep Playwright for deterministic end-to-end suites in CI. ego(lite) covers the agent-driven browser work around them, from investigation and search to live checks and data collection.

When to use each tool

Choose ego(lite) when

  • The work lives behind your logins: dashboards, admin panels, SSO, and scripting storageState isn't worth it.
  • You'd rather describe the task to Claude Code, Codex, or Cursor than scaffold a test project and maintain locators.
  • You want several flows checked in parallel Spaces while you keep browsing in the same browser.
  • You care about per-task token cost: Snapshot input plus batched JavaScript, stacked, keeps whole tasks cheap.

Choose Playwright when

  • You're building committed end-to-end test suites that run deterministically in CI. That's Playwright's core strength.
  • You rely on its test runner, auto-waiting, trace viewer, and codegen, tooling most competitors still lack.
  • You need Firefox and WebKit coverage. ego(lite) is Chromium only.
  • Your team works across TypeScript, Python, Java, or .NET and wants first-class bindings in each.

Compare ego(lite) with other browser automation tools

Side-by-side comparisons with Puppeteer, Playwright MCP, Claude Chrome extension, Browser Harness, and 7 more.

FAQ

What is Playwright?

Playwright is Microsoft's open-source automation framework for Chromium, Firefox, and WebKit, with first-class bindings for TypeScript, Python, Java, and .NET. Its test runner, auto-waiting, trace viewer, and CI integration are the strongest in the category, and for committed, deterministic end-to-end test suites it's the tool to beat. Microsoft has also started shipping playwright-cli, a token-conscious companion CLI from the Playwright team for coding agents like Claude Code and Copilot. This page is about the core framework and its scripting and CLI workflows; Playwright MCP, the separate agent-facing MCP server, has its own comparison page. Developers picking an agent-driven approach also weigh Browser Use vs Playwright and Stagehand vs Playwright, since all three show up in most LLM-driven browsing stacks.

Is ego(lite) a good Playwright alternative?

For AI-agent-driven browser work, yes: no scripts, real logins, parallel Spaces, making it one of the few Playwright alternatives built specifically for agents rather than more scripting. For committed end-to-end test suites in CI, no. Playwright's test runner, tracing, and cross-browser coverage are genuinely excellent, and you should keep using them. The honest split: Playwright for tests you commit, ego(lite) for tasks you delegate.

How was the ego(lite) vs Playwright benchmark run?

Both ran the same 31 complex real-world browser automation tasks on live websites, driven by the same pi agent with the same model (gpt-5.6-sol, thinking effort max) and graded by the same judge against per-task rubrics; every score covers all 31 tasks. Playwright entered through playwright-cli, the companion CLI the Playwright team ships for coding agents, which is the strongest agent-facing way to run it today. ego(lite) finished 93.5% of tasks perfectly at $1.75 per completed task, 63% faster on average task time; agent-driven Playwright finished 71% at $4.82. The harness, the tasks, the rubrics, and the raw results are open source in the ego-browser-benchmark-framework repository on GitHub, so every number can be audited or reproduced.

Playwright vs Puppeteer vs Selenium: which should I use?

All three are script-first frameworks, whether you search it as playwright vs puppeteer or puppeteer vs playwright. Playwright wins for new test suites: fastest runner, auto-waiting, TS/Python/Java/.NET, all three engines. Puppeteer wins when you're Chrome-only in Node and want a lean DevTools-level API. Selenium wins where the W3C WebDriver standard, broad language bindings, or an existing enterprise Grid matter. ego(lite) fills a different role: an AI agent does the browsing instead of a script, with no code to maintain and your real logged-in profile already attached.

Playwright vs Selenium: pros and cons?

Selenium vs Playwright comes down to trade-offs on both sides. Playwright: faster execution, built-in auto-waiting, a modern test runner, and tooling like trace viewer and codegen; the trade-off is a younger ecosystem. Selenium: the W3C WebDriver standard, the widest language and legacy-browser coverage, and two decades of enterprise adoption; the trade-off is more verbose code and more explicit wait management. If you're choosing a test framework today, most teams pick Playwright. If the work is agent-driven rather than scripted, see how ego(lite) compares to Selenium on our Selenium page.

What about Playwright MCP or playwright-cli for AI agents?

Both wrap a fresh Playwright browser for agent use, and both still run one command per action in a blank profile: Playwright MCP as MCP tool calls, playwright-cli as CLI invocations. ego(lite) instead batches multiple actions in JavaScript per turn, reads pages as compressed Snapshots, and starts from your real logged-in Chrome profile. Across those 31 live-site jobs that difference measures out to 93.5% of tasks perfect against 71%, at $1.75 per completed task against $4.82 and 63% faster on average task time, with playwright-cli as the Playwright entrant. Full breakdown on the ego(lite) vs Playwright MCP page.

Can Playwright use my existing Chrome logins?

Partially. You can save storageState after a scripted login, or launch a persistent context pointed at a Chrome profile directory, but sessions expire, 2FA and SSO interrupt scripted logins, and a profile can't be shared with a running Chrome. ego(lite) imports your profile once, and the agent inherits real login state from then on.

Is ego(lite) free?

Yes. Free, no subscription, data stored locally. The ego-browser shell your agent connects through is MIT-licensed open source.

Why are Playwright tests flaky in CI, and how do I fix them?

CI flake usually comes from shared state, unstable selectors, race conditions, resource pressure, or a test that assumes a fixed delay. Use isolated fixtures, locator-based assertions, waits for meaningful application state, bounded retries for diagnosis, and trace artifacts. ego(lite) is not a CI test-runner replacement: its visible Spaces help an agent investigate an interactive failure, while Playwright remains the right choice for committed deterministic suites.

Can ego(lite) or Playwright bypass Cloudflare, CAPTCHA, or Akamai?

No tool can guarantee that, and this page does not provide bypass instructions. A block is an access-control decision: respect the site's terms, robots and rate limits, use an official API or licensed feed, request permission, or stop. ego(lite) can use your own authorized browser session for content you can already see, but a real Chrome profile, residential IP, stealth plugin, or mouse simulation is not a promise of access and must not be used for ban evasion.

Is there a Playwright alternative with fewer brittle selectors?

For interactive, agent-driven work, ego(lite) lets the agent read the current page and choose an action instead of maintaining a generated selector for every one-off task. That reduces script maintenance, but it does not make a changing site magically stable: keep source-linked results, verify important fields, and retain Playwright for assertions and repeatable CI coverage. For Playwright itself, prefer roles, labels, test IDs, and stable application contracts over generated CSS classes.

Can an AI agent write and fix E2E tests in plain English?

An agent can turn a plain-English scenario into Playwright code, run the suite, inspect a trace, and propose or apply a fix in a controlled branch. It still needs a clear assertion contract, test data, and human review: an agent can make a test green by weakening an assertion or masking a product bug. ego(lite) is useful for exploring a flow in a real session; promote verified behavior into committed Playwright tests when it must run in CI.

How should Playwright alternatives handle third-party iframes and dynamic content?

Treat an iframe as a separate browsing context and wait for the frame or application state that proves it is ready; do not rely on arbitrary sleeps. For Stripe-like third-party checkout, use the provider's supported test mode and stable labels, and keep secrets out of fixtures. An agent can inspect a live frame and recover from a changed layout, but it cannot remove cross-origin restrictions or guarantee that a provider's UI will remain available.
Give your agent a real browser

Free, runs on your computer, imports your Chrome profile in one click. Works with Claude Code, Codex, Cursor, and any CLI agent that writes code.