Is Claude Fable 5.2 worth switching to for browser agents?

We would recommend a switch to Claude Fable 5.2 if your browser agent currently runs on 5.1. It's faster, cheaper and more accurate. In our Claude Fable 5.2 vs 5.1 test, we ran each model once on the same 28 web tasks, Fable 5.2 passed 89.3% of them and Fable 5.1 passed 82.1%. On the tasks both models passed, Fable 5.2 took 418.5 seconds and $2.63 per task, against 450.6 seconds and $3.28 for Fable 5.1.
- When collecting the same details from several official websites, Fable 5.2 cost less on average and had a slightly highly success rate.
- For workflows inside a single web app, both models passed all 4 attempts, and Fable 5.2 cost less per task.
- However, if your primary task is open-ended research, Fable 5.1 cost slightly less while maintaining the same success rate as Fable 5.2.
| Model | Success rate | Time per passed task | Cost per passed task | Cost per passed attempt |
|---|---|---|---|---|
| Claude Fable 5.2 | 89.3% (25/28) | 418.5 s | $2.63 | $3.13 |
| Claude Fable 5.1 | 82.1% (23/28) | 450.6 s | $3.28 | $4.85 |
Where Fable 5.2 finishes what its predecessor couldn't
Both Fable models are strong browser agents, so we tested them on everyday jobs with demanding requirements. One was choosing a work phone: build a spec sheet for nine flagship phones, with many fields per phone, from each maker's own site. On the OnePlus 15 overview page, the IP ratings appear only inside a product image with no alt text. Both models opened that page in ego(lite). Fable 5.2 took a screenshot of the image and read all four ratings, IP66, IP68, IP69 and IP69K.
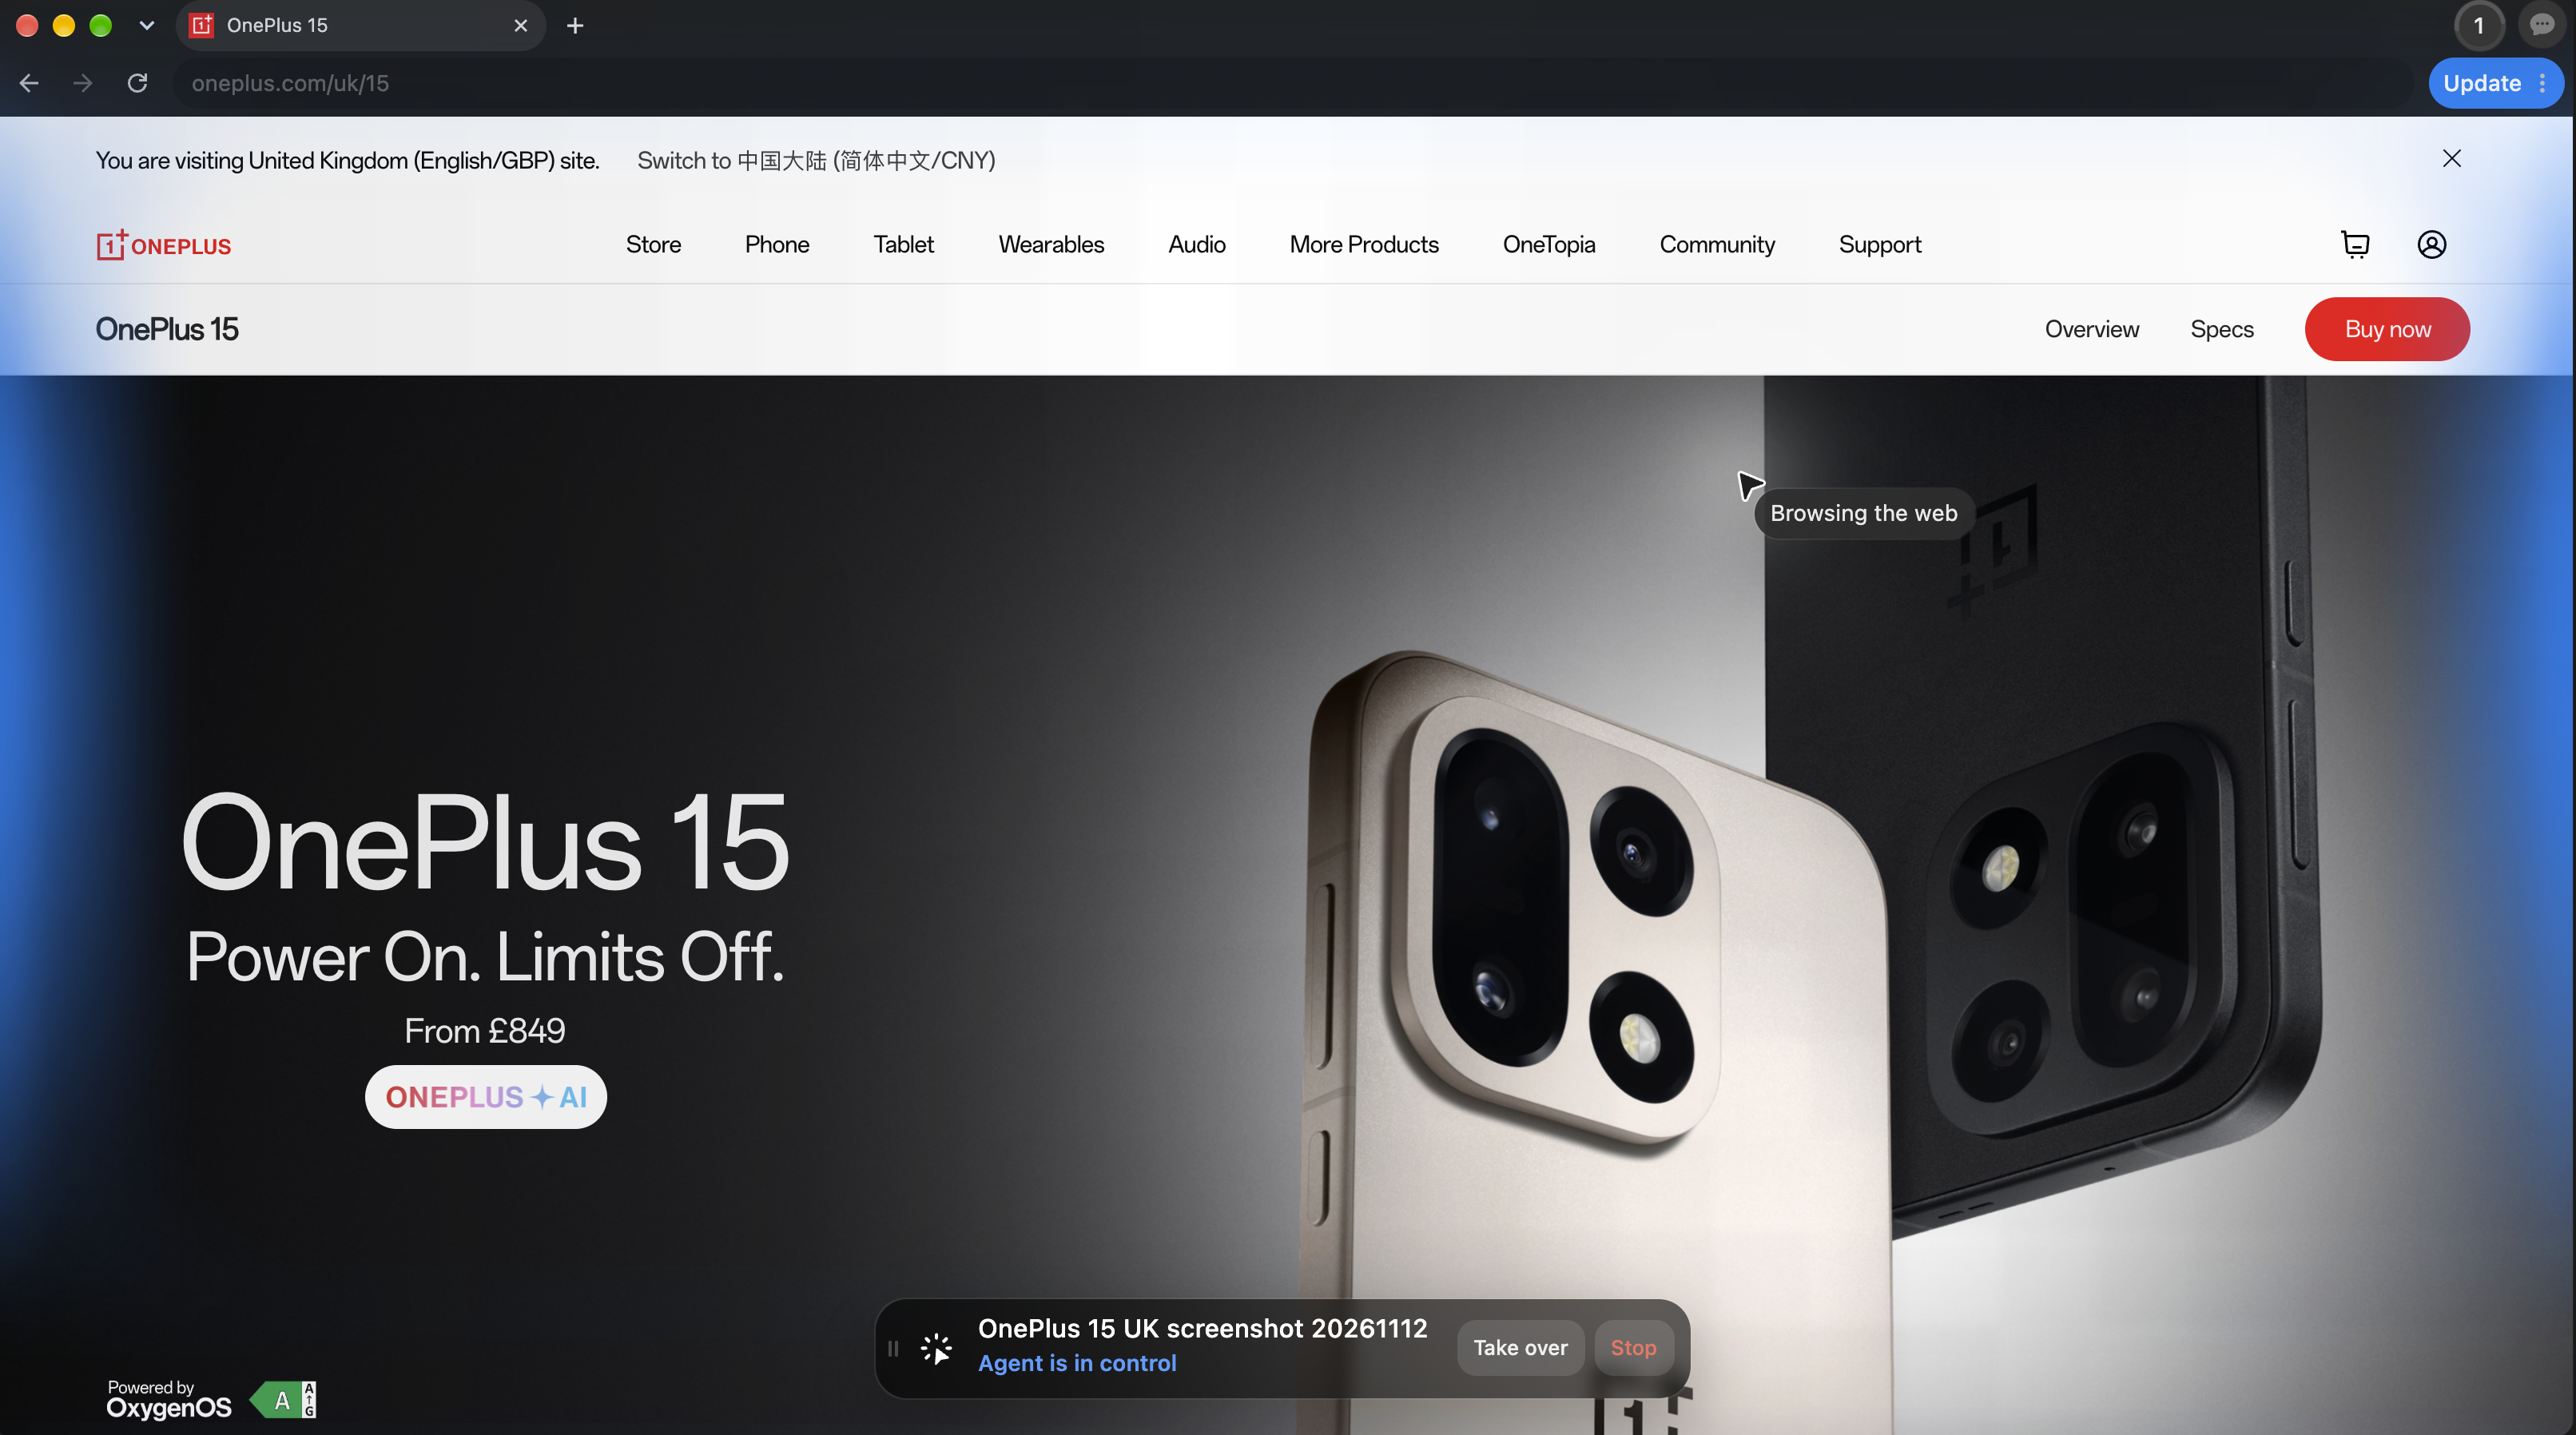
Fable 5.1 searched the same page's text for IP codes and found none. It then took IP68 from an eco-design line on the specs page. Its final table gave the OnePlus 15 one rating, so the phone was also missing from its list of IP69 devices. Fable 5.2 made 65 tool calls on this task and Fable 5.1 made 31, so the right answer cost $6.04 against $3.13.
Where Fable 5.1 is doing a good enough job
Fable 5.1 is a capable browser agent, and staying on it still makes sense. It passed every web app workflow and research task, such as booking travels, filling purchase orders and tracing information sources. If your agent mostly handles tasks such as those, switching won't bring a dramatic increase in finished tasks. What you'd actually gain is a lower price about 20%. However, Fable 5.2 remains the better option if your agent frequently fills long spec sheets or comparison tables across multiple sites. In these cases, a missing or wrong value is usually difficult to spot.
Why Fable 5.2 is cheaper
Fable 5.2 is cheaper mostly because Anthropic lowered the asking price. Its list prices are 20% lower for every kind of token compared to Fable 5.1. It is also the biggest reason why we recommend a switch. Because in terms of efficiency, the two did about the same amount of work to finish a task. Fable 5.2 wrote about 18% fewer output tokens per task but made a few more tool calls, 35 against 32, so the two cancel out. Priced at Fable 5.1's rates, its bill would come out the same.
In a browser agent, you mostly pay for the model to read, not write. About 70% of Fable 5.2's spend went to its context: the page text, snapshots and screenshots it pulled in, plus its earlier steps, which it reads back on every turn. That's why jobs that span too many sites often cost the most. Collecting the same details from 8 to 12 official sites cost $4.65 per task with Fable 5.2, while a lookup across up to three sites cost $1.35. We'd budget by the kind of work your agent does, not by the model's price alone.
The bigger saving shows up per usable result. When a task went wrong, Fable 5.1 spent more before it stopped, so about a third of its total went to attempts that failed, against an eighth for Fable 5.2. Counting those failures, each passed attempt cost $4.85 with Fable 5.1 and $3.13 with Fable 5.2. That's the number we'd look into while comparing the cost.
Show as table
| Type of work | Fable 5.2 passed | Fable 5.1 passed | Fable 5.2 cost per task | Fable 5.1 cost per task | Tasks in cost |
|---|---|---|---|---|---|
| All task types | 25/28 | 23/28 | $2.63 | $3.28 | 23 |
| Multi-site data collection | 9/10 | 8/10 | $4.65 | $5.77 | 8 |
| Search and compare | 8/8 | 7/8 | $1.35 | $1.84 | 7 |
| Web app automation | 4/4 | 4/4 | $1.44 | $1.84 | 4 |
| Research and synthesis | 3/3 | 3/3 | $2.02 | $1.87 | 3 |
| Social media verification | 1/3 | 1/3 | $1.96 | $3.32 | 1 |
How to run it
We ran claude-fable-5-2 with reasoning effort high in Claude Code, with the Bash, Read, Write, Edit and Skill tools. The agent loads the ego-browser skill file and drives ego(lite) through ego-browser. It writes short JavaScript scripts that ego-browser runs to control pages in ego(lite).
FAQ
Is Claude Fable 5.2 better than Fable 5.1 for browser agents?
In our tests, yes: Claude Fable 5.2 passed every task Fable 5.1 passed, plus two more. On 28 web tasks, run once each in the same agent harness and browser tool, Fable 5.2 passed 25 of 28 attempts (89.3%) and Fable 5.1 passed 23 of 28 (82.1%). One of the extra passes was a spec sheet where Fable 5.2 read IP codes from a product image.
Is Claude Fable 5.2 worth upgrading to from Fable 5.1?
Yes, Claude Fable 5.2 is worth the upgrade for browser agents, because it cost less for the same work and lost no task Fable 5.1 passed. It passed 25 of 28 attempts against 23 of 28 for Fable 5.1. On the 23 tasks both models passed, it cost $2.63 per task against $3.28, which is Anthropic's 20% price cut.
Is Claude Fable 5.2 cheaper per task than Fable 5.1, or only per token?
Claude Fable 5.2 is cheaper per task as well as per token: $2.63 against $3.28 on the 23 web tasks both models passed. Its list prices are 20% lower for every kind of token. Priced at Fable 5.1's rates, its usage on those tasks would cost about $3.28, so the per-task saving on finished work is the price cut.
Does Claude Fable 5.2 use fewer tokens than Fable 5.1?
Across all 28 attempts, Claude Fable 5.2 used 29% fewer output tokens, 20,138 per attempt against 28,481 for Fable 5.1. On the 23 tasks both models passed, it still wrote fewer output tokens, 18,581 per task against 22,607. Priced at the same rates, its total usage on those tasks cost about the same as Fable 5.1's.
Is Claude Fable 5.2 faster than Fable 5.1 on browser tasks?
Yes, slightly: on the 23 web tasks both models passed, Claude Fable 5.2 took 418.5 seconds per task and Fable 5.1 took 450.6 seconds. Fable 5.2 was faster on 13 of those 23 tasks. Both ran in the same agent harness and browser tool, and the time includes waiting for the model API.
How much does Claude Fable 5.2 cost to run as a browser agent?
In our tests, Claude Fable 5.2 cost $2.63 per task on average on the 23 web tasks both models passed, and $3.13 per passed attempt counting all 28 attempts. Fable 5.1 cost $3.28 per task and $4.85 per passed attempt. Multi-site data collection was the most expensive type of work, at $4.65 per task for Fable 5.2.
What is Claude Fable 5.2 good at in browser automation?
Claude Fable 5.2 passed every web app automation, search and compare, and research attempt in our tests, and 9 of 10 multi-site data collection attempts. Fable 5.1 passed 8 of 10 multi-site attempts and 7 of 8 search and compare attempts. Fable 5.2's two extra passes came in those two types of work.
Where does Claude Fable 5.1 still match Fable 5.2?
Claude Fable 5.1 matched Fable 5.2 on web app workflows and open-ended research. Both models passed all 4 web app automation attempts and all 3 research and synthesis attempts. On research, Fable 5.1 cost $1.87 per task against $2.02, while on web app workflows Fable 5.2 was cheaper at $1.44 against $1.84.
Does Claude Fable 5.2 stop before finishing multi-step browser tasks?
Not in our tests: every Claude Fable 5.2 attempt ended with a final answer, and none used up the 100-step budget. Its three failures were final answers that didn't get every required value right.
Can Claude Fable 5.2 run browser tasks unattended?
Claude Fable 5.2 finished most tasks on its own, passing 25 of 28 attempts, but each of its three failures still ended with a final answer that had errors in it. Twice it took values from the wrong source, such as a later security release or another regional press release. For release or pricing data, check which page each value came from.
How can Claude Fable 5.2 use a browser?
Claude Fable 5.2 can drive a browser through an agent harness and a browser tool. In our tests it ran in Claude Code and drove ego(lite) through ego-browser, writing short JavaScript scripts that ego-browser ran to control pages. With that setup it passed 25 of 28 attempts on web tasks.
How we tested
We compared Claude Fable 5.2 (claude-fable-5-2) and Claude Fable 5.1 (claude-fable-5-1), both at reasoning effort high, in the same agent harness: Claude Code with the Bash, Read, Write, Edit and Skill tools. Both drove ego(lite) through ego-browser, which gives the model the page as an accessibility snapshot, page text or a screenshot, whichever the model's script asks for. We ran the tests on November 12, 2026, on Linux.
The 28 tasks cover five types of work. Web app automation means workflows in test business apps, such as matching invoices to payments. Search and compare covers one to three sites, such as checking browser support on MDN and Can I use. Multi-site data collection means the same fields from 8 to 12 official sites, such as rate decisions from 12 central banks. Research and synthesis is open-ended, such as tracing a Wikipedia table to its sources. Social media verification matches X posts to official pages. Each task belongs to one type.
Each model ran each task once, and one run of a task is an attempt. An attempt passes when its final answer gets every required value right. Each attempt had 100 steps and 60 minutes at most. A step is one model turn, a tool call is one call the model makes to a tool, and a browser command is one script handed to ego-browser. Time is wall-clock time per attempt, including the time spent waiting for the model API. Cost is in US dollars, computed from each attempt's token usage at Anthropic's list prices, with cache reads and cache writes at their own rates. Time and cost per passed task are compared on the 23 tasks both models passed. Cost per passed attempt divides the cost of every attempt by the number of passed attempts.
Full results
Each cell shows whether the model's one attempt passed, how long it took in seconds, including waiting for the model API, and what it cost in US dollars. Averages elsewhere use unrounded costs.
| Task | Type of work | Claude Fable 5.2 | Claude Fable 5.1 |
|---|---|---|---|
| Book flights, seats and a hotel under a travel policy in a booking app | Web app automation | Passed · 220.0 s · $1.66 | Passed · 208.2 s · $2.19 |
| Bring service monitors up to a written standard in a monitoring app | Web app automation | Passed · 140.7 s · $1.02 | Passed · 158.2 s · $1.60 |
| Create purchase orders from stock levels in an inventory app | Web app automation | Passed · 163.0 s · $1.06 | Passed · 128.2 s · $1.29 |
| Match February invoices to payments and open disputes in a finance app | Web app automation | Passed · 316.3 s · $2.02 | Passed · 308.8 s · $2.28 |
| Check a lecture video's chapters against its GitHub code and arXiv paper | Search and compare | Passed · 136.3 s · $1.14 | Passed · 221.8 s · $1.57 |
| Compute inflation figures from FRED and confirm them on BLS | Search and compare | Passed · 122.7 s · $1.03 | Passed · 93.3 s · $1.11 |
| Cross-check browser support for six web features on MDN and Can I use | Search and compare | Passed · 179.2 s · $1.14 | Passed · 239.1 s · $2.13 |
| Find the cheapest nonstop fares for three cities on a flight search site | Search and compare | Passed · 683.0 s · $2.24 | Failed · 768.3 s · $4.41 |
| Match Phase 3 trials on ClinicalTrials.gov to their DailyMed labels | Search and compare | Passed · 178.6 s · $1.52 | Passed · 267.6 s · $2.24 |
| Price and compare three laptop configurations on a maker's US store | Search and compare | Passed · 378.2 s · $2.46 | Passed · 392.0 s · $3.17 |
| Reconcile six films' box office between a box-office database and Wikipedia | Search and compare | Passed · 102.2 s · $1.09 | Passed · 87.6 s · $1.12 |
| Screen four UK companies on Companies House | Search and compare | Passed · 101.2 s · $1.09 | Passed · 185.4 s · $1.52 |
| Build a compliance matrix from 9 SaaS trust centers | Multi-site data collection | Passed · 1110.0 s · $6.16 | Passed · 737.9 s · $5.56 |
| Collect five specs for 8 cameras from makers' sites | Multi-site data collection | Passed · 482.4 s · $3.49 | Passed · 480.9 s · $4.35 |
| Collect five specs for 9 flagship phones from makers' UK sites | Multi-site data collection | Passed · 992.6 s · $6.04 | Failed · 467.5 s · $3.13 |
| Collect opening keynote details for 9 developer conferences | Multi-site data collection | Passed · 920.8 s · $4.85 | Passed · 1168.4 s · $8.85 |
| Collect range and charging figures for 9 electric SUVs from makers' US sites | Multi-site data collection | Passed · 1120.9 s · $6.91 | Passed · 1261.0 s · $6.91 |
| Collect specs and licenses of 9 open-weight models from Hugging Face and vendor pages | Multi-site data collection | Passed · 758.7 s · $5.24 | Passed · 1059.6 s · $6.26 |
| Collect statutory minimum wages from 9 labor agencies | Multi-site data collection | Passed · 567.0 s · $4.25 | Passed · 640.1 s · $5.32 |
| Collect the first 2026 rate decision from 12 central bank sites | Multi-site data collection | Passed · 525.9 s · $3.51 | Passed · 435.1 s · $4.52 |
| Compare free tiers of 9 serverless platforms | Multi-site data collection | Passed · 501.1 s · $2.77 | Passed · 665.2 s · $4.40 |
| Compare one album's listing on 9 music services | Multi-site data collection | Failed · 408.6 s · $1.98 | Failed · 292.4 s · $2.22 |
| Count models over EU compute thresholds in a public model database | Research and synthesis | Passed · 195.2 s · $1.64 | Passed · 80.4 s · $1.08 |
| Read cost and score points off an interactive leaderboard chart | Research and synthesis | Passed · 317.1 s · $2.39 | Passed · 327.3 s · $2.41 |
| Trace 10 cells of a Wikipedia table to their sources | Research and synthesis | Passed · 382.2 s · $2.03 | Passed · 342.7 s · $2.12 |
| Match 8 brands' product posts on X to their press releases | Social media verification | Failed · 1132.7 s · $3.79 | Failed · 2200.8 s · $14.22 |
| Match 8 open-source projects' X security posts to their own announcements | Social media verification | Failed · 750.8 s · $3.75 | Failed · 3302.8 s · $12.30 |
| Match a week of SpaceX launch posts on X to Wikipedia's launch lists | Social media verification | Passed · 706.2 s · $1.96 | Passed · 875.8 s · $3.32 |