Short answer: Playwright and Cypress are both designed to turn known browser workflows into repeatable tests. Playwright provides broader control over multiple pages, iframes, browser contexts, and browser engines, while Cypress places more emphasis on its interactive Runner and tightly integrated debugging experience. Although they differ in capability and workflow, both are better suited to stable processes that can be described in advance with selectors, actions, and assertions.
This shared assumption matters more than many feature-by-feature comparisons. When a workflow must run repeatedly and the application is controlled by the team, deterministic browser testing is the right fit. But when the website interface, execution environment, or task objective can change during the run, maintaining the test script can sometimes take more effort than completing the task itself, which is where a full Chromium like ego (lite) lets an agent work against the live page, cross-origin iframes and all.
Is Playwright better than Cypress?
For a greenfield end-to-end suite, Playwright is usually the safer default because its browser-context, page, frame, tracing, and parallel-worker primitives cover more application shapes without restructuring the product under test. That recommendation changes when the team depends on Cypress component testing, already has a healthy Cypress suite, or gets more value from the Cypress runner than it would gain from Playwright's broader browser-control model.
| Constraint | Prefer Playwright | Prefer Cypress |
|---|---|---|
| Several tabs or popups | Pages are first-class objects | Usually redesign the test into one controlled tab |
| Cross-origin iframe | Frame locators can target it | Outside cy.origin() support |
| Component feedback loop | Supported, but project fit varies | A core Cypress workflow |
| Existing healthy suite | Migrate only for a measured gap | Keep it if constraints are met |
How do their execution models differ?
Playwright's test process controls browsers through its automation protocol. A test creates a browser, one or more isolated contexts, and pages inside those contexts. New pages and popups remain addressable, and each context can carry its own cookies, permissions, and storage. The test and the application are separate processes, which makes cross-page orchestration explicit.
Cypress coordinates a Node process, a proxy, and code running with the application in the browser. That architecture powers its live command log, DOM snapshots, time-travel debugging, and direct application feedback. It also explains why Cypress keeps control in one primary browser tab and asks tests to enter a second top-level origin through cy.origin().
Architecture is not a quality score. It is a constraint map. A checkout that embeds a cross-origin payment frame and opens a receipt window places different demands on a runner than a single-origin dashboard with rich component tests.
Which browser workflows can each test?
| Workflow | Playwright | Cypress |
|---|---|---|
| Multiple tabs/windows | Direct page and popup events | No commands in another tab/window; keep the flow in one tab or test the destination separately |
| Top-level origin change | Navigate and locate normally | Use cy.origin() for commands on the secondary origin |
| Cross-origin iframe | Use frameLocator or contentFrame | Not handled by cy.origin() |
| Network observation | Events, routing, and response waits | cy.intercept(), aliases, waits, and stubs |
| Isolated sessions | Several browser contexts in one browser | Test isolation resets state between tests; session caching can restore selected setup |
The important correction is that Cypress is not simply ‘single-origin.’ Current Cypress supports top-level cross-origin testing with cy.origin(). The narrower boundaries are that cy.origin() does not operate a cross-origin iframe, and Cypress does not execute commands in a different browser tab or window. Those distinctions should drive fixture design and tool choice.
How do waiting and retries differ?
Playwright separates actionability waiting, assertion retry, and whole-test retry. Before actions such as click, it checks conditions such as visibility, stability, event reception, and enabled state. Its web-first assertions retry until they pass or time out. Test retries are a separate runner setting and were disabled in our experiment.
Cypress chains queries and assertions and reruns that linked query chain while the assertion can still succeed. A non-query command such as click executes once; Cypress does not replay every preceding command because a later assertion failed. Whole-test retries are also separate and default to zero unless configured.
What happened in our controlled test?
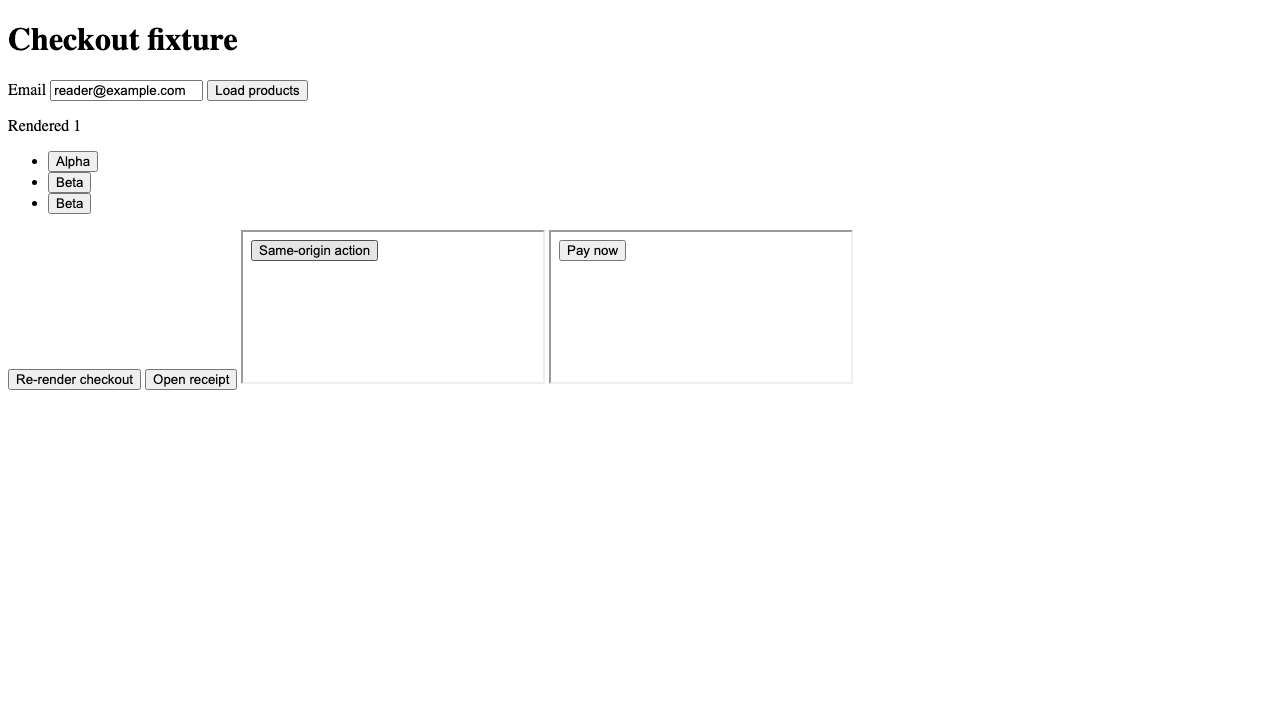
We built a two-origin fixture with delayed product data, duplicate labels, a replaced status node, an intentional HTTP 503, a same-origin iframe, a cross-origin payment iframe, and a receipt popup. The common task covered only capabilities available to both tools. Additional tests made the architecture boundary visible instead of quietly deleting hard cases.
| Observed result | Playwright 1.63.0 | Cypress 16.0.0 |
|---|---|---|
| Shared in-tab workflow | 3 of 3 passed | 3 of 3 passed |
| Cross-origin iframe | 3 of 3 passed | Explicitly pending: documented model boundary |
| New-tab receipt | 3 of 3 passed | Explicitly pending: test must be restructured |
| Retries | 0 | 0 |
The first Playwright attempts failed before navigation because its matching Chromium binary was absent. After installing the pinned browser, all reruns passed. We kept the failed logs because setup failures are part of migration cost. We did not turn the later wall-clock difference into a speed claim: each runner used a different browser binary and startup path, and three trials on one laptop are not representative of CI.
What did the live-site Playwright pass add?
On September 14, 2026, we ran one additional headed Playwright 1.63.0 pass against IKEA US. The test started from the home page, searched for desk through the visible search field, applied the White filter, and selected Price: low to high. IKEA reported 111 filtered items and loaded 24 product cards in the grid we inspected. The first two complete white desks priced at $200 or less in that loaded set were TORALD at $29.99 and MICKE at $69.99. We excluded legs, tabletops, drawer units, clothes rails, and other accessories.
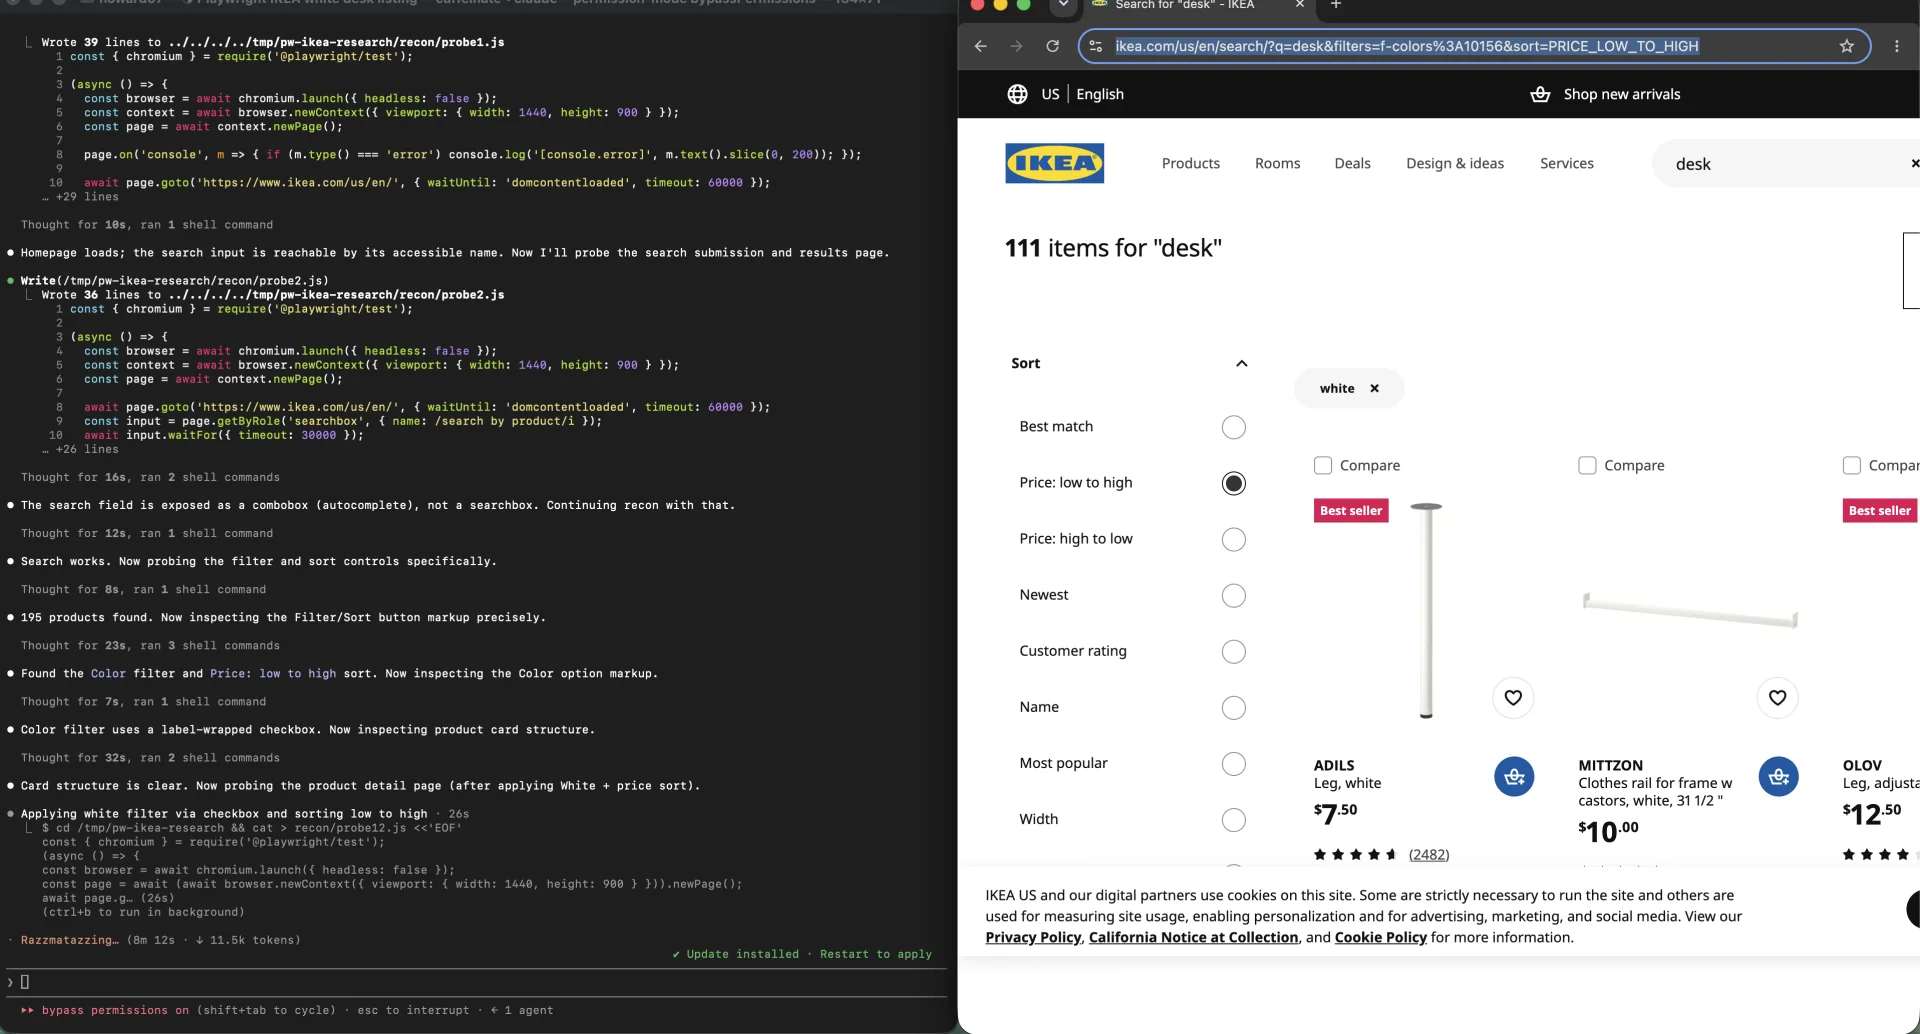
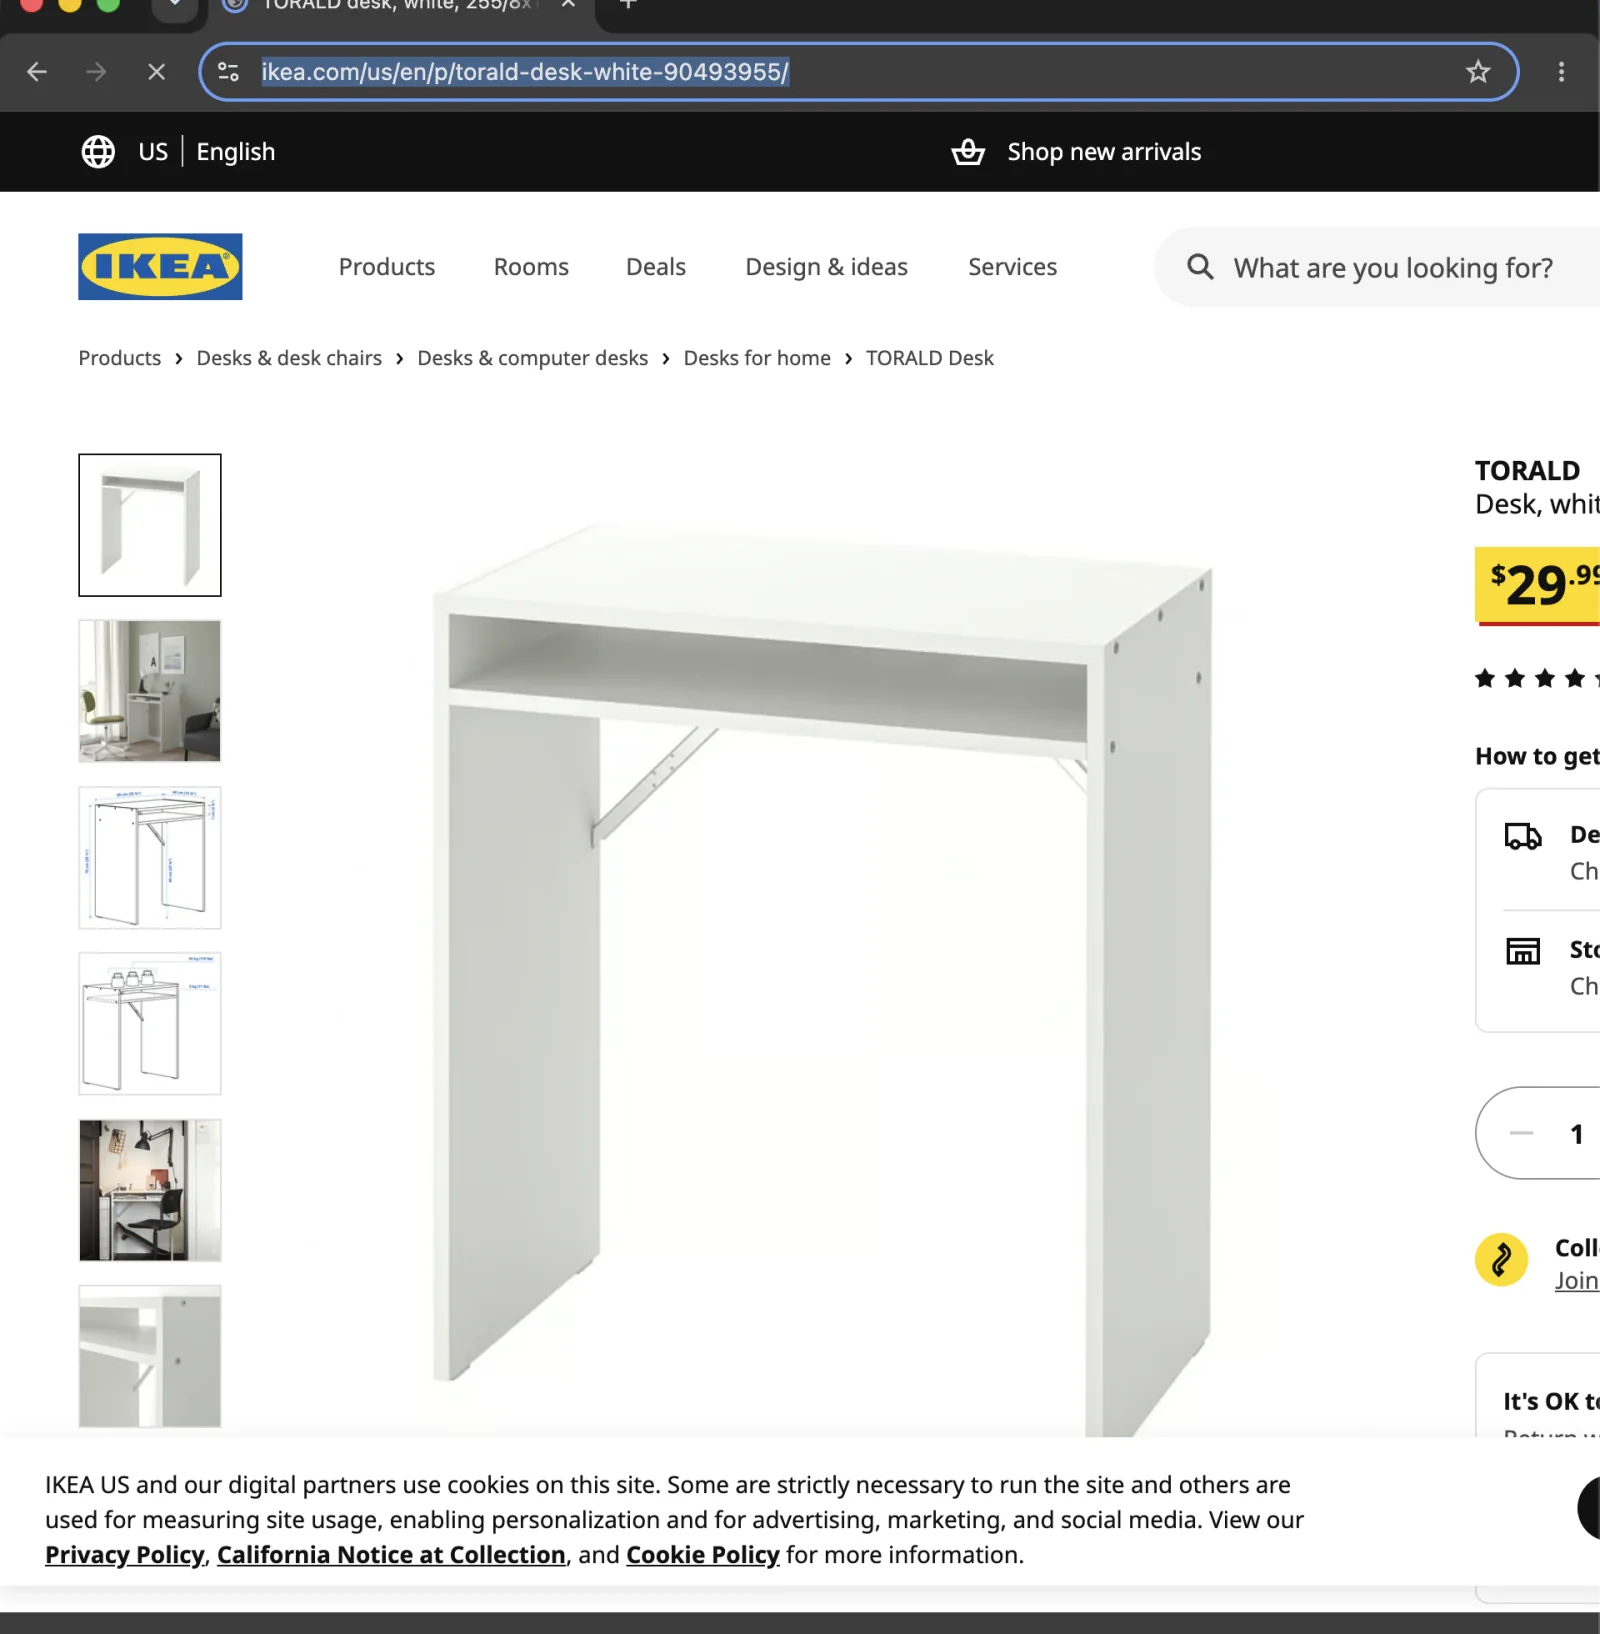
The test then opened TORALD from its product card and matched the detail-page name and $29.99 primary price to the listing. After returning to the results, the desk query, White filter, low-to-high sort, and leading price were still present. That verifies one real navigation and state-retention path. It does not claim that the test evaluated all 111 filtered items.
What happened in the live-site Cypress pass?
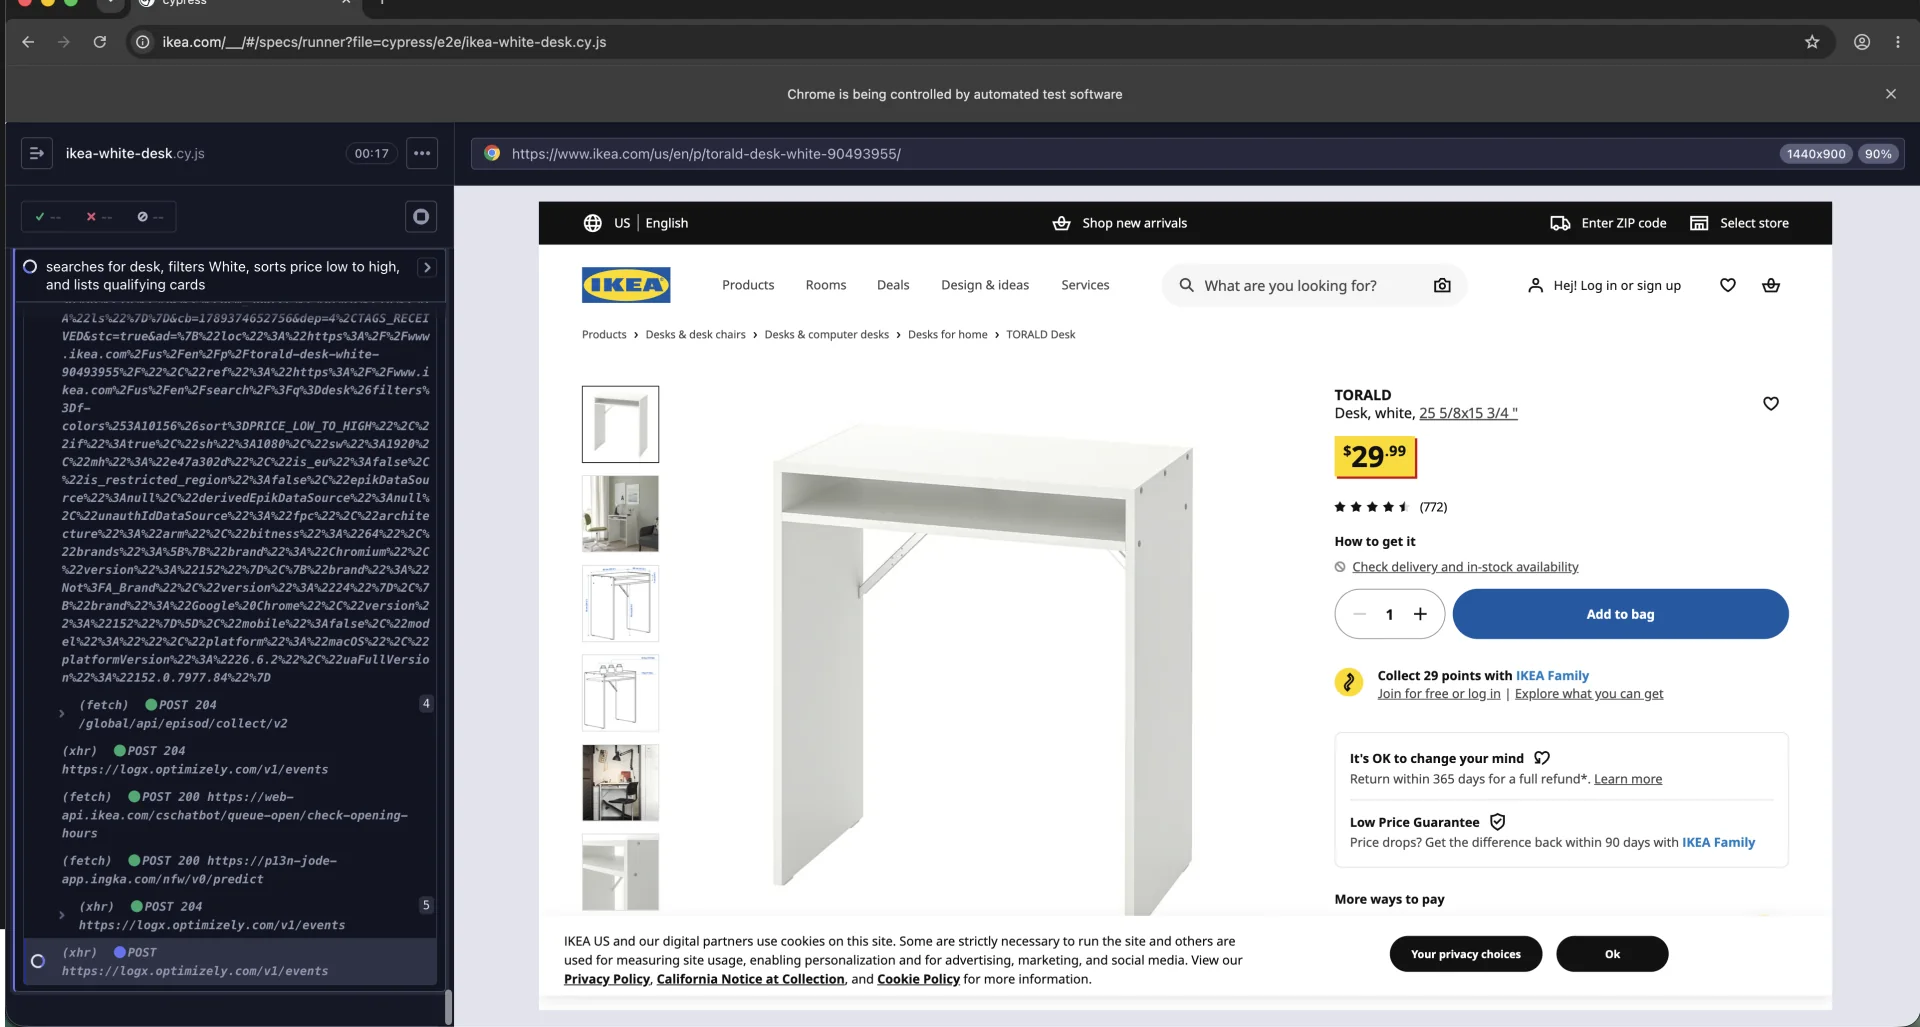
Cypress completed the captured search, White filter, Price: low to high sort, product-detail check, and return-state assertions in headed Chrome with retries disabled. It identified the same first two complete desks in the loaded filtered grid: TORALD at $29.99 and MICKE at $69.99. The native Runner kept the command log, one passing test, the active White filter, and the selected sort visible together.
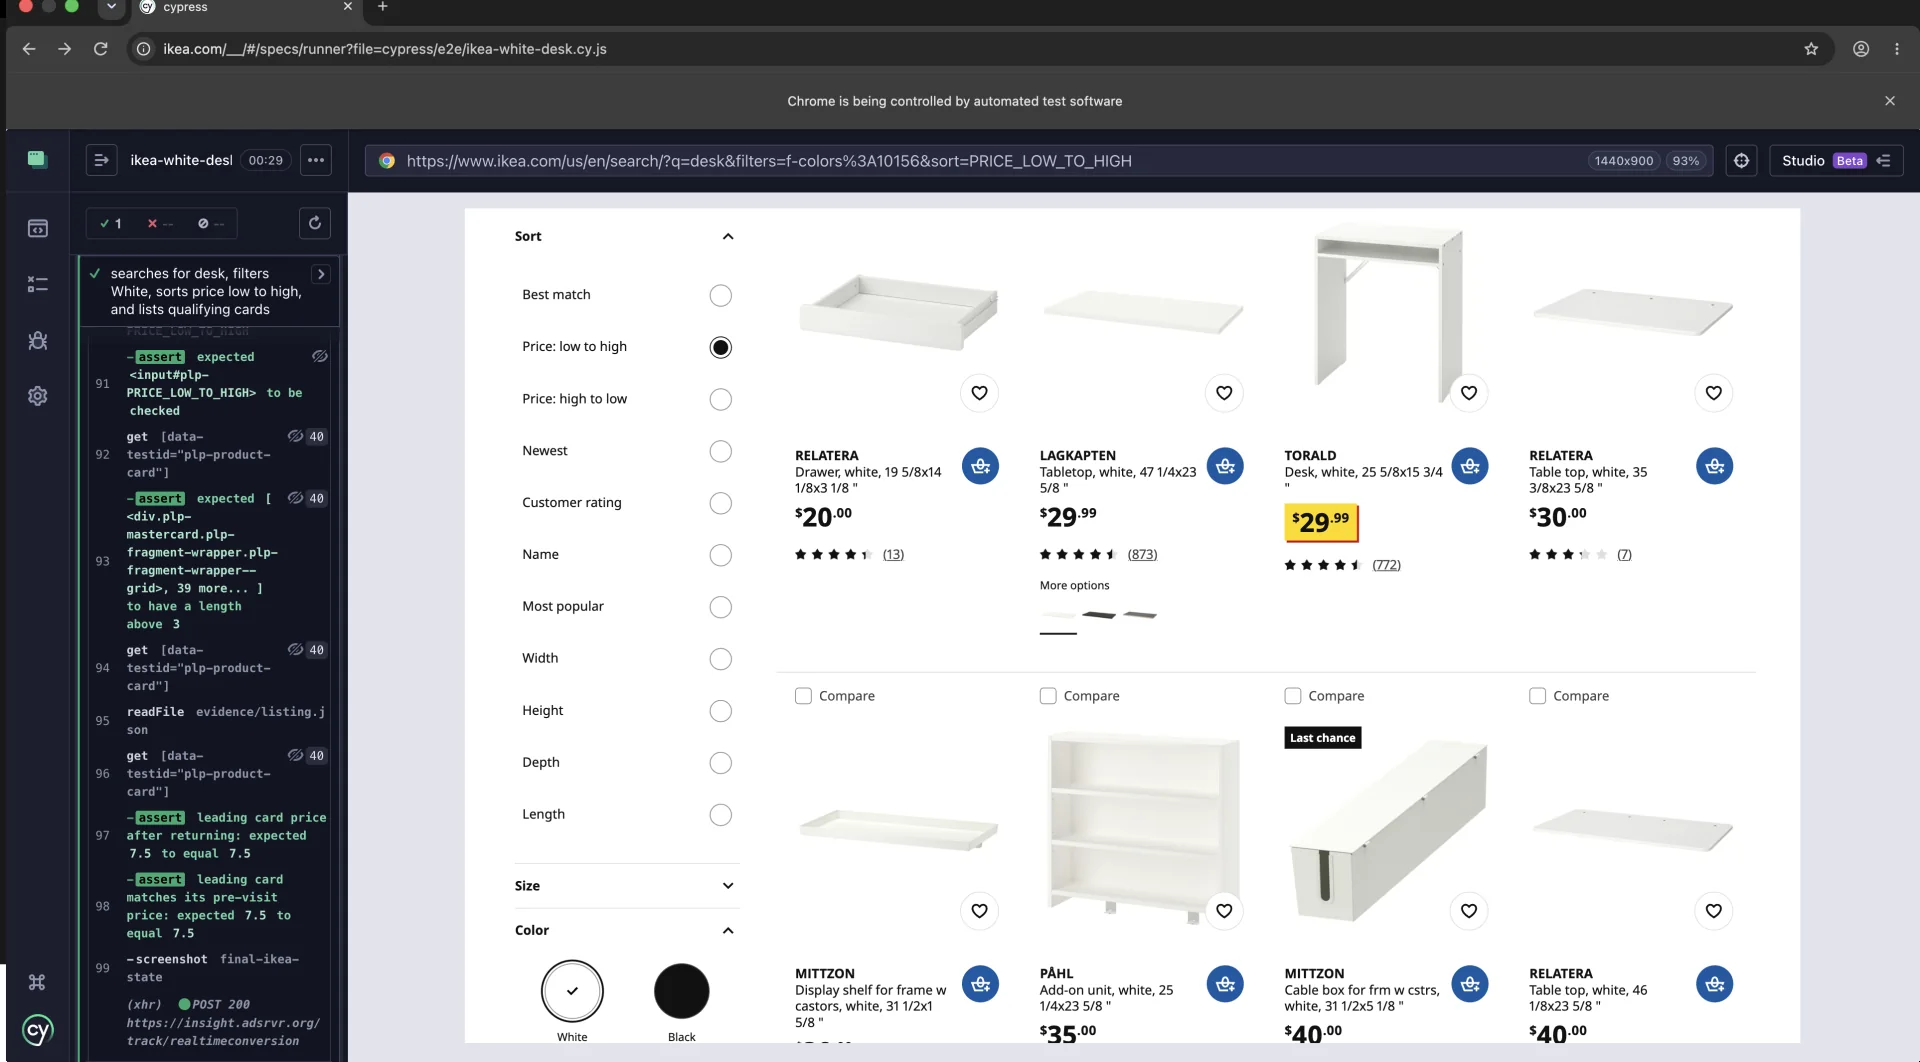
The clean result still required one site-specific workaround. IKEA renders the color choice as a styled label around a visually hidden checkbox. During authoring, Cypress's actionability check rejected ordinary clicks against the layered swatch, so the final spec used click({ force: true }) on the label. It then verified the checked input, the filter in the URL, and a grid dominated by white product descriptions. We count the task as completed with an actionability workaround, not as a friction-free default interaction.
What changed when we used ego (lite)?
The same IKEA task used a different operating model with ego (lite) 0.5.0.31. We gave Claude Code the goal in natural language and connected it to one visible ego (lite) Space. Claude Code translated that request into live browser actions without us authoring a reusable Playwright or Cypress test spec. The Space kept its identity and the controls Agent is in control, Take over, and Stop visible throughout the run.
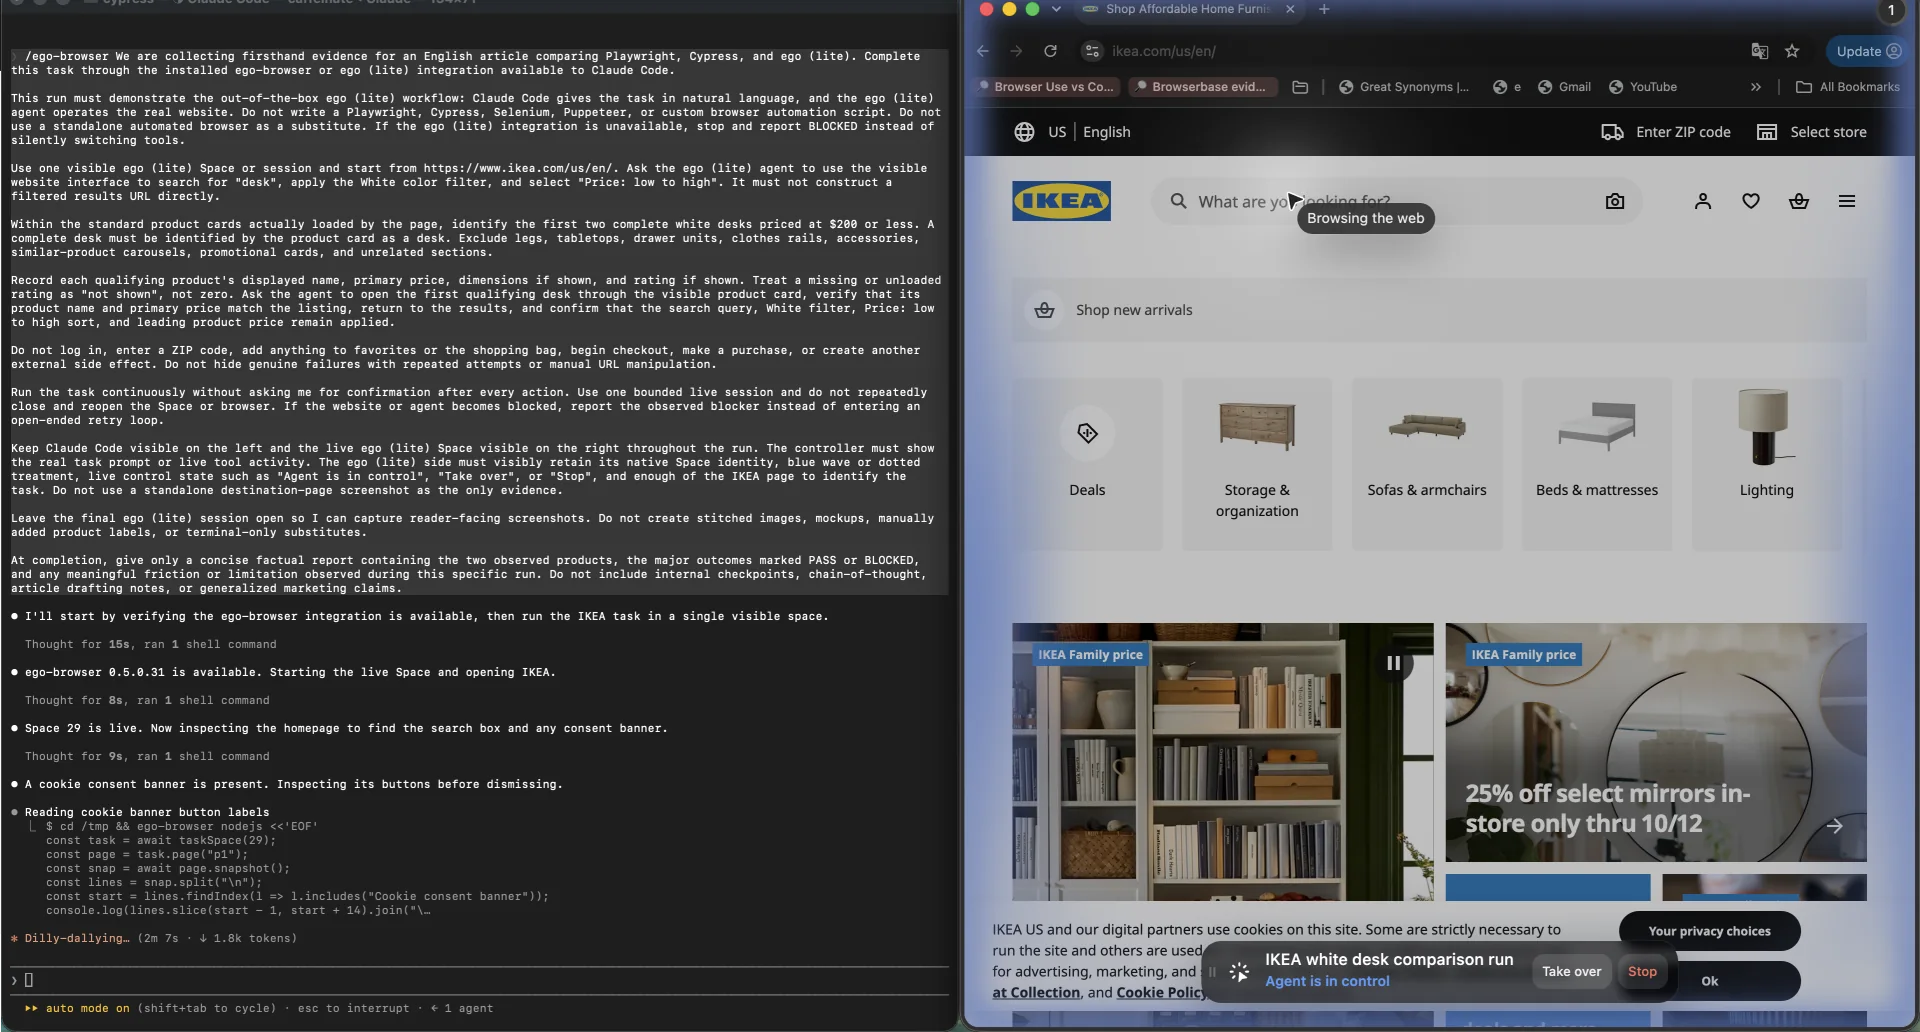
The agent searched for desk, applied the White filter, selected Price: low to high, and inspected the 40 product cards loaded in the page DOM. It found the same first two qualifying complete desks, TORALD at $29.99 and MICKE at $69.99, with their ratings. It then opened TORALD through the visible product card, verified the name and primary price, returned to the results, and confirmed that the query, White filter, URL sort parameter, and ascending prices remained. It did not claim coverage beyond those 40 loaded cards.
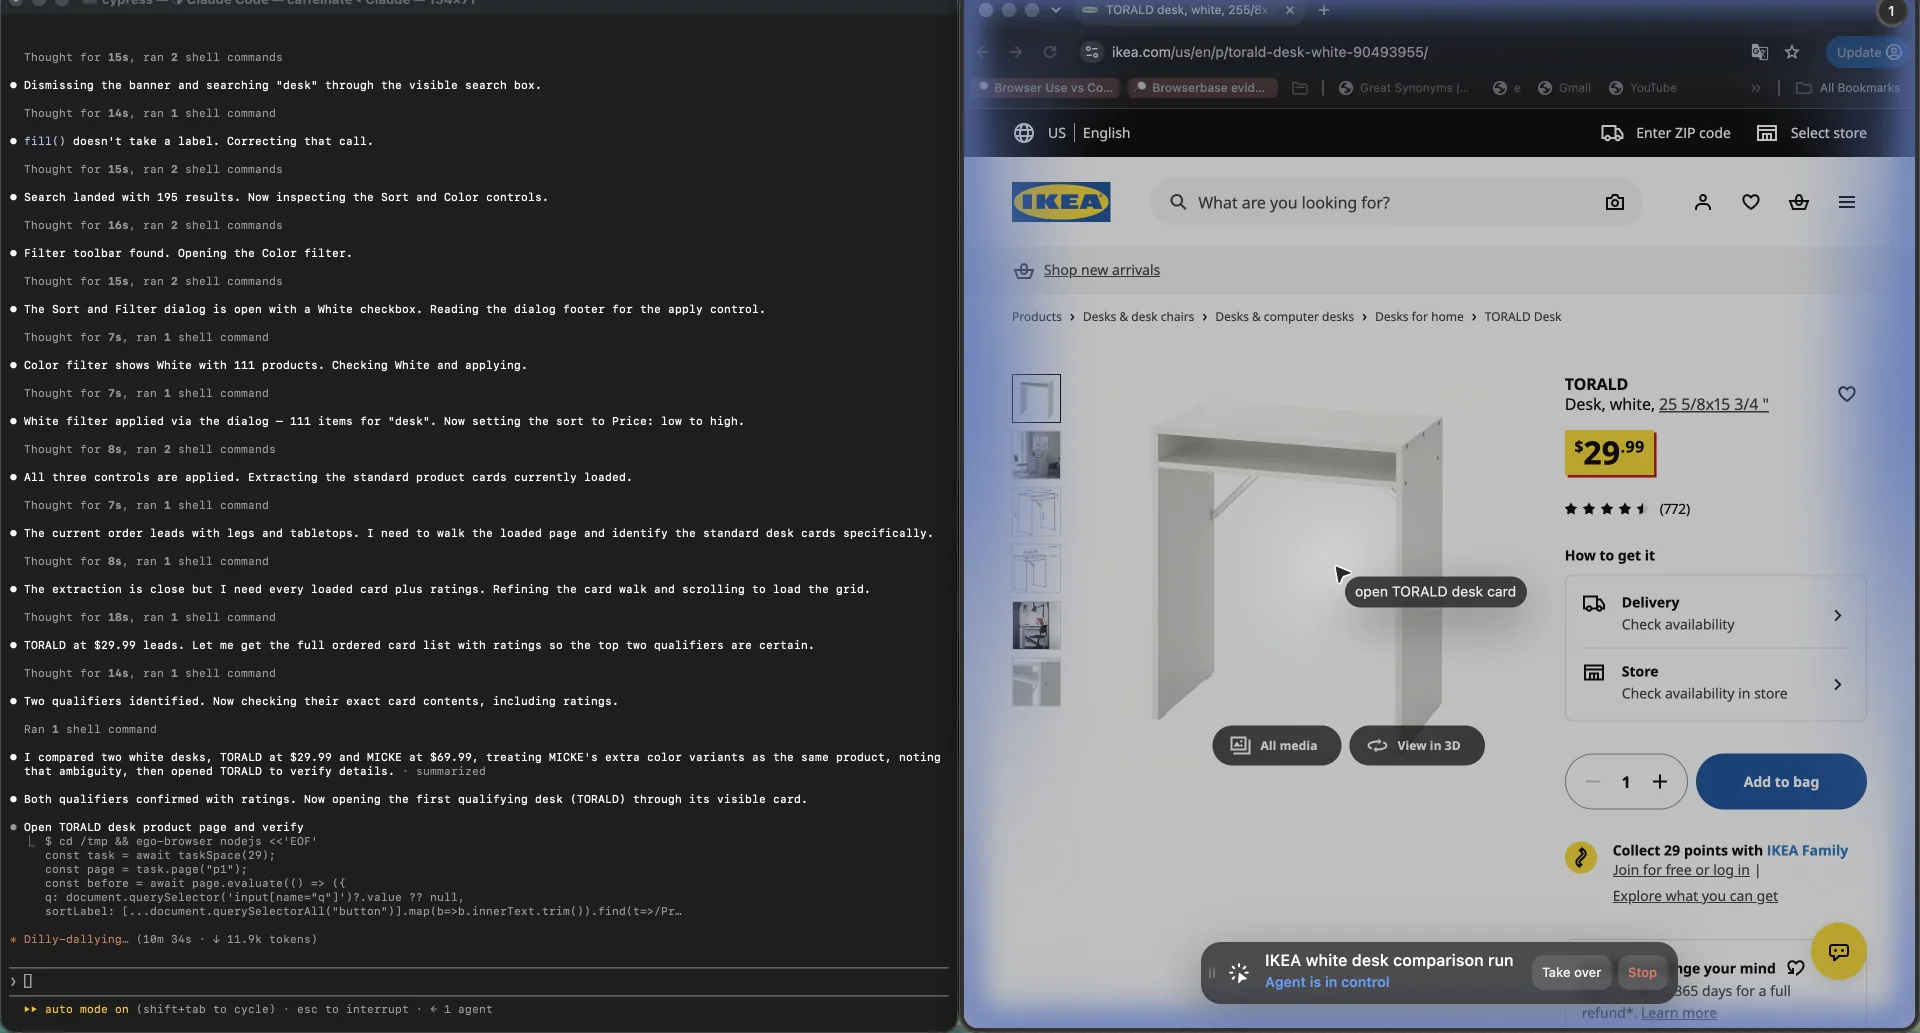
That difference is the practical decision point. Playwright and Cypress ask you to encode a durable, repeatable test. ego (lite) lets you start with an outcome in natural language and supervise the agent in a visible Space. That is useful for one-off or changing, authorized browser work where writing and maintaining a full test spec would cost more than the task. It is not a substitute when the result must become a deterministic CI gate.
How did the three hands-on sessions feel?
For this narrow evidence-gathering job, ego (lite) felt fastest, Playwright came second, and Cypress was very slow. That ranking describes the whole working session, including reconnaissance, authoring, debugging, reruns, and collecting screenshots. It is not a measurement of browser-engine speed or the runtime of an already-finished test suite.
ego (lite) reached the useful answer directly from a natural-language goal and kept the real page visible while it worked. Playwright took longer because the session first mapped the page and then built and corrected a durable test, but the finished artifact was deterministic and came with a trace. Cypress exposed every step clearly in its Runner, yet the session spent substantially more time reconciling IKEA's layered color control, asynchronous grid, and Runner lifecycle with a test framework designed for authored, repeatable checks. For this one-off research task, that was a poor fit rather than proof that Cypress is generally slow.
| Observed order | Approach | Visible working window | What the session produced |
|---|---|---|---|
| 1, fastest in this session | ego (lite) | About 13 minutes | Completed the live task in one visible Space from a natural-language request; no reusable test spec |
| 2 | Playwright | About 25 minutes | Completed a reusable test, one bounded headed pass, and a retained trace after reconnaissance and one assertion correction |
| 3, slowest in this session | Cypress | About 54 minutes | Completed the live task in the Runner after repeated interaction fixes, asynchronous-grid debugging, and Runner restarts |
How do debugging and CI compare?
Cypress's interactive runner is unusually good at showing the command sequence and captured DOM state while a developer works in the browser. Playwright's trace viewer reconstructs actions, DOM snapshots, network activity, console output, attachments, and timing after or during a run. Which feels better depends on whether your team debugs primarily in a live runner or from retained CI artifacts.
Both can parallelize and produce CI artifacts. Compare the open-source runners separately from optional paid dashboards, hosted orchestration, analytics, or test-impact products. Your CI decision should include worker startup, browser caching, sharding, artifact retention, quarantine policy, and how quickly a developer can reproduce a failed job locally.
Which framework should you choose?
Choose Playwright when any of these are non-negotiable:
- The same journey must coordinate popups, several pages, or several browser contexts.
- A cross-origin iframe is part of the release-critical flow.
- Chromium, Firefox, and WebKit coverage should use one integrated runner and API.
- Trace-first failure analysis and highly isolated parallel workers fit the CI model.
Choose or keep Cypress when these are more important:
- The application is primarily a single-tab frontend and its critical flows fit the documented origin model.
- Component testing and an in-browser command log are central to the team's daily feedback loop.
- The current Cypress suite is healthy, trusted, and cheaper to maintain than replace.
- The team already has stable fixtures, custom commands, CI dashboards, and debugging habits around Cypress.
How do you migrate from Cypress to Playwright?
- Inventory capabilities before syntax. Mark every use of cy.origin(), cy.intercept(), custom commands, sessions, tasks, component mounts, plugins, and cloud-only features.
- Select five to ten journeys that represent login, data setup, network behavior, frames, downloads, popups, and the slowest CI path.
- Rebuild state boundaries. Map Cypress hooks and cy.session() to Playwright fixtures, projects, browser contexts, and storageState without sharing mutable accounts across workers.
- Translate intent, not chaining syntax. Prefer role, label, and test-id locators; replace implicit subject chains with named locators and explicit assertions.
- Match network semantics. Decide whether each intercept is observing, waiting, stubbing, or mutating, then implement the equivalent route or response wait.
- Run both suites against the same build and seed data. Compare uncovered requirements, failure causes, authoring time, triage time, and infrastructure work.
- Migrate only after the representative slice meets an agreed reliability and debugging contract. Keep a rollback window instead of rewriting the entire suite at once.
// Cypress
cy.contains("button", "Load products").click();
cy.get('[role="status"]').should("have.text", "Ready");

// Playwright
await page.getByRole("button", { name: "Load products" }).click();
await expect(page.getByRole("status")).toHaveText("Ready");
Where does ego (lite) fit?
The IKEA run makes the choice concrete. Playwright and Cypress are the better tools when a team needs a versioned spec, exact assertions, repeatable fixtures, and a CI result. ego (lite) is the better fit when the work starts as a natural-language goal, the path may change as the real site responds, and a person should be able to watch or take over the authorized browser Space.
In this case, ego (lite) completed the same search, filter, sort, inspection, detail check, and return-state check without a reusable selector-heavy test file. That reduces setup for bounded, one-off work, but it does not remove the need for judgment or turn the run into regression coverage. Keep release assertions, fixtures, isolation, and CI gates in Playwright or Cypress. Do not automate destructive account actions, bypass MFA, or reuse a personal profile where a dedicated test account is the safer boundary.
What are the limits of this comparison?
The controlled comparison used one macOS arm64 machine, local HTTP servers, Chrome-family browsers, three post-setup trials, and no retries. The later IKEA checks added one headed Playwright run, one headed Cypress run, and one visible ego (lite) Space run. They were not added to the framework scorecard. Neither experiment measured a production suite, WebKit, Firefox, component testing, visual regression, paid cloud services, memory use, or large-scale parallelism. Version changes can alter behavior, so verify current documentation and rerun the fixture before making a high-cost migration decision.
Which official sources support the comparison?
For Playwright, verify the current documentation for pages and popups, actionability, network control, and test retries.
For Cypress, use its current documentation for retry ability, cy.origin(), and its documented cross-origin and multi-tab boundaries. All links and package versions were checked on September 11, 2026.
FAQ
Is Cypress flaky?
Not inherently. Cypress retries queries and assertions, but bad selectors, shared data, external dependencies, and incorrect command boundaries can still create flaky tests.
Can Cypress test multiple domains?
Yes, for supported top-level origin transitions using cy.origin(). That support does not extend to a cross-origin iframe, and Cypress does not run commands in a second tab or window.
Does Playwright retry every failed action?
No. Playwright auto-waits before actions and retries web-first assertions. Whole-test retries are a separate configuration. A side-effecting action is not blindly replayed because a later assertion failed.
Should an existing Cypress suite migrate?
Only when a representative pilot proves that a real capability, maintenance, coverage, or debugging gap is worth the rewrite and infrastructure cost.